
Google’s Gemini 4 Argon takes on the engineering work around robots
Google’s Real2Sim experiment points to a faster path from a workspace observation to useful robot practice, with better results on physical hardware.
At a glance
- Google widened developer access to Gemini 4 Argon on October 13.
- Google reports robot success rising from 56% to 75% after fine tuning with simulated data.
- Argon scored 87% on ERQA, leading the frontier models in Google’s comparison.
What happened
Google widened access to Gemini 4 Argon on October 13 and demonstrated a robotics workflow that turns a single workspace photograph into simulation data for training a robot policy.
The model was first announced on September 30 with restricted access. The October release opens it to developers through the paid Gemini API and expands access across Google’s products. VentureBeat also reported the broader rollout on October 13.
For robotics, the interesting development is the work between observing a task and teaching a machine to perform it. Black Scarab’s reading is that Argon could make parts of that engineering loop easier to repeat: build an environment, generate practice, improve a policy and test the result on hardware.
A picture becomes a practice environment
In Google’s tabletop example, Argon constructs a calibrated MuJoCo twin from one overhead RGB photograph. The workspace contains two Franka FR3 arms and party props. The prompt specifies 77 tasks, including placing objects, uprighting them and passing them between arms.
Argon then creates a motion generator and collects more than 4,500 simulated episodes, varying object positions by up to 10 centimeters. The episodes are intended for fine tuning a vision language action model, or VLA.
A VLA is the policy that connects visual observations and task instructions with robot actions. In this workflow, Argon helps construct its practice material. That division gives developers two things to evaluate: the quality of the generated environment and the behavior learned from it.
An episode records a sequence of observations and actions as a task unfolds. Useful practice therefore needs more than a recognizable scene. The generated movements must interact with objects in ways that teach the policy something it can use when it returns to the physical workspace.
Black Scarab Weekly
Follow the physical AI economy
Get Black Scarab news, deep research, and practical analysis in one clear Thursday briefing.
The simulation has to behave convincingly
MuJoCo is a physics engine for simulating articulated systems and their contact with the environment. Its documentation describes models built from bodies, joints, collision geometry and other parameters, with simulation advancing the physical state over time.
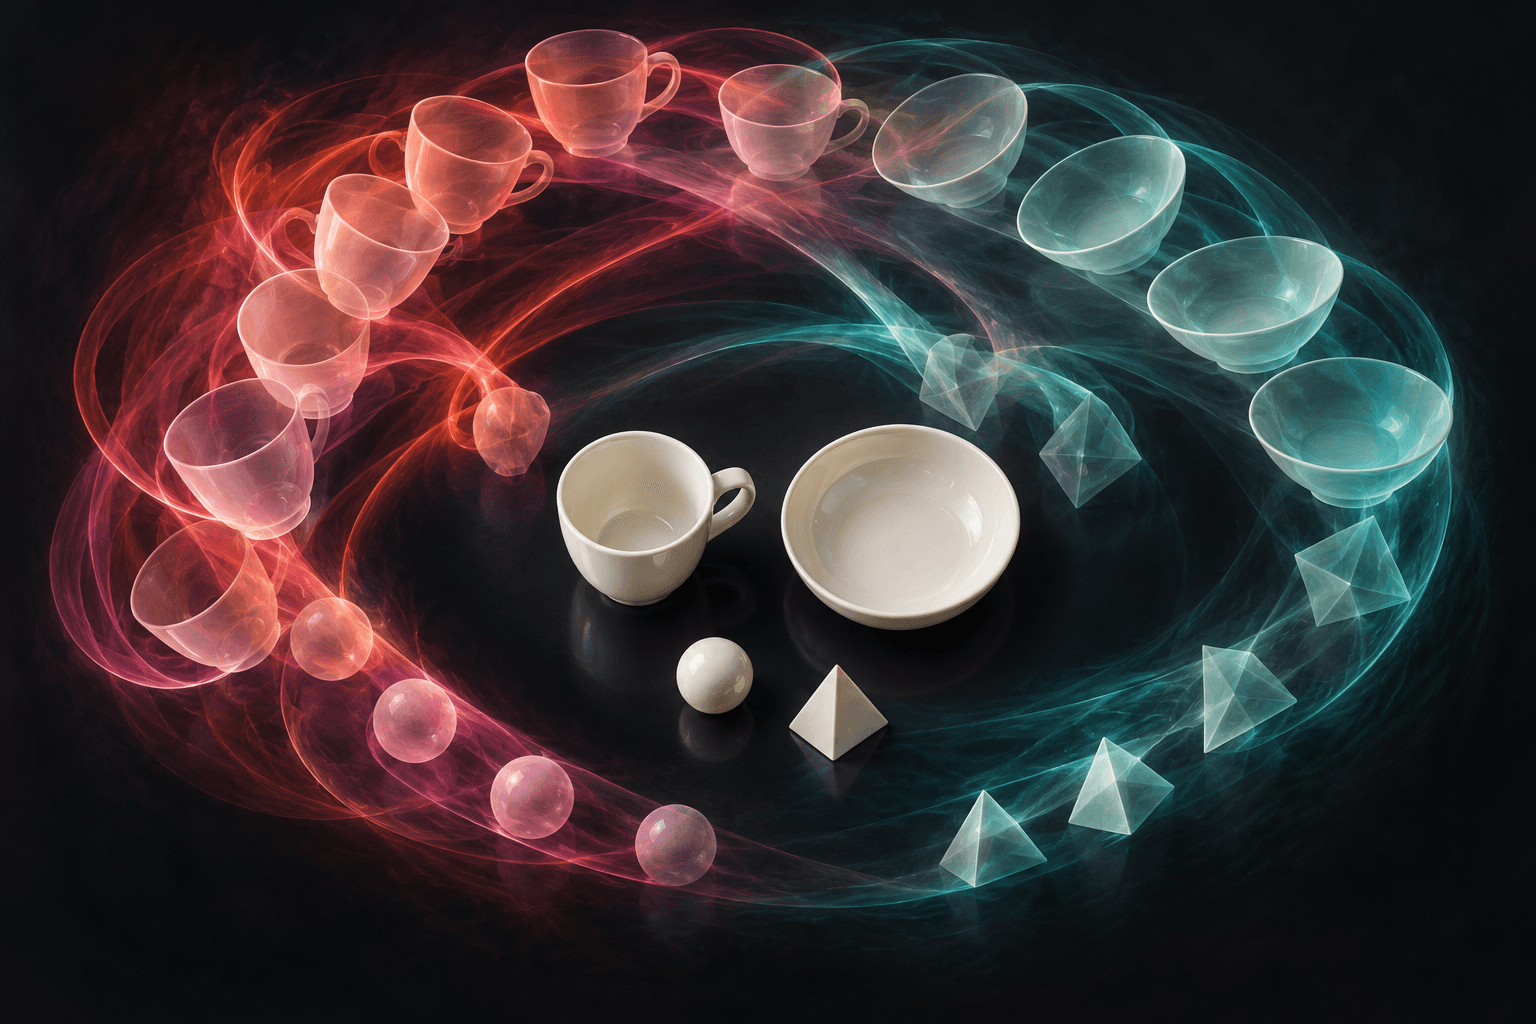
A cup illustrates the challenge. Its visible surface helps describe what a camera sees. Its collision shape helps determine where a gripper or another object can touch it. Friction influences whether it slips. Mass and inertia influence its response to movement.
The engineering task is to make those descriptions useful together. A bowl represented as a solid block might resemble its outer silhouette, yet behave incorrectly when a robot tries to place an object inside it. A convincing visual reconstruction can still produce misleading practice.
A static photograph also leaves physical properties underdetermined. Two similar looking objects can have different weights or surface friction. Our analysis is that generated twins need physical testing and correction wherever those differences affect the task.
Variation makes practice more useful
Domain randomization is an established approach to helping models transfer from simulation to reality. In a 2017 paper, Josh Tobin and colleagues varied simulated visual conditions so that a real observation could fall within the range a model had already encountered. Their experiment concerned object localization for robotic manipulation.
The principle is straightforward: practice should include variation. Repeating exactly the same starting arrangement can reward a policy for learning one narrow sequence. Moving objects or changing conditions makes it confront different observations while pursuing the same goal.
For an engineering team, the choice of variation becomes part of the design. The training environment should cover changes the robot will actually encounter. Too narrow a range leaves brittle behavior; arbitrary variation can consume effort without improving the task that matters.
This is where automation could help. If building another scene or curriculum becomes easier, developers can spend more iterations testing which practice changes improve performance. The useful output is a policy that transfers, and hardware evaluation remains the way to judge it.
The result is meaningful within its test
Google reports real robot success increasing from 56% to 75% after the simulation data was used, while completion time fell from 35 to 24 seconds. Those are results from the company’s tabletop evaluation.
The success improvement is 19 percentage points. The time reduction is 11 seconds. Both calculations describe the reported comparison; they should be kept separate when assessing what improved.
Faster successful movements can be useful, but an operating process also includes failed attempts, recovery and the time between tasks. A developer evaluating this approach should measure the whole sequence under consistent conditions, including the human intervention needed to finish the work.
The reported endpoint also leaves substantial room for improvement. A 75% success rate means one quarter of attempts were unsuccessful in that evaluation. For a task that must run repeatedly, reducing those failures and making recovery dependable are practical parts of the next engineering step.
What the reasoning score tells us
ERQA is a multimodal question answering benchmark released by Google DeepMind. Its repository describes 400 examples, with images and text presented as multiple choice questions about spatial reasoning and world knowledge in robotic scenarios.
That format measures how a model answers questions about a scene. Physical execution adds contact, timing, sensing and feedback. A strong reasoning score can help identify a promising model for development work, while robot trials establish whether the complete system performs the intended task.
The two forms of evidence are useful together. Scene reasoning supports environment construction and diagnosis. Repeated physical trials test whether the resulting assumptions and learned behavior survive contact with the real workspace.
Where the commercial opportunity sits
Black Scarab’s analysis is that the immediate opportunity lies in making task development more repeatable. A robotics team could use generated simulations to explore a new arrangement, produce candidate practice data and compare policy updates before committing more hardware time.
Consider a hypothetical team adapting a manipulation cell to several tray layouts. A faster route to candidate environments could let it test more arrangements. The relevant commercial question would be whether that process reduces the engineering effort required to reach dependable behavior across the layouts.
Integrators could benefit if more of that work can be reused between projects. They would still need to define the task, connect the software to the actual robot and assess performance under customer conditions. Their expertise could shift toward specifying and validating the process while automated tools handle more environment construction.
This also changes where differentiation might emerge. If simulation creation becomes more accessible, valuable advantages could come from better task definitions, stronger evaluation sets, useful recovery behavior and accumulated knowledge of what transfers across real installations.
A practical test for developers
A useful pilot would begin with one task and a measured baseline. Keep a set of real starting conditions outside the generated training set, then compare the original and updated policies under the same hardware and success criteria.
Record successful completions, failures, recovery time and engineering hours. Inspect cases where simulation predicts success but the physical robot fails. Those cases reveal which parts of the environment or behavior need correction.
The economics should include the whole development loop. Google lists introductory API prices of $2 per million input tokens and $10 per million output tokens through November 30. Its announcement says standard rates will then become $4 and $20 respectively.
Model usage is one input to a pilot budget. Simulation, policy training, hardware trials and engineering review also take resources. The attractive outcome would be less total effort to reach a defined level of real performance, with enough reusable work to make the next task easier.
What to watch next
The next useful evidence is repeated transfer across different objects, layouts and tasks. Particularly telling would be a team using the same workflow on successive projects while spending less time correcting each new environment.
Watch how failures are diagnosed and fed back into simulation. A process that can identify a mismatch, revise the environment and produce better practice data would strengthen the case for a durable development tool.
Argon’s robotics demonstration gives a concrete reason to examine the engineering around the policy. If that work becomes faster to repeat, developers could reach useful robot behavior through more frequent, better directed cycles of practice and physical testing.
Sources and further reading
- Google Developers Blog, Gemini 4 Argon for Robotics, October 13, 2026
- Google, broader Gemini 4 Argon release and introductory pricing, October 13, 2026
- Google, original Gemini 4 Argon announcement, September 30, 2026
- Google DeepMind ERQA repository and evaluation harness
- MuJoCo documentation, physics simulation overview
- Tobin and colleagues, Domain Randomization for Transferring Deep Neural Networks from Simulation to the Real World, 2017
- VentureBeat, broader Argon availability, October 13, 2026
- Interesting Engineering, coverage of Google’s robotics and scientific demonstrations, October 13, 2026
About the author
Rodolfo is the founder of Black Scarab, where he covers the technologies and commercial signals shaping physical AI adoption.
Meet Rodolfo